• Skip to primary navigation
  • Skip to content
  • Skip to footer
Jongha Kim
Home Research CV Notes

[프로젝트] Scene graph to Video generation with diffusion model - (0)proposal

November 1, 2024

Inha univ. Scene Graph를 Condition으로 받는 video generation diffusion model

🎈 SG2Video 개념 정리한 페이지 바로가기 🎈
🎈 SG2Video 구현 정리한 페이지 바로가기 🎈
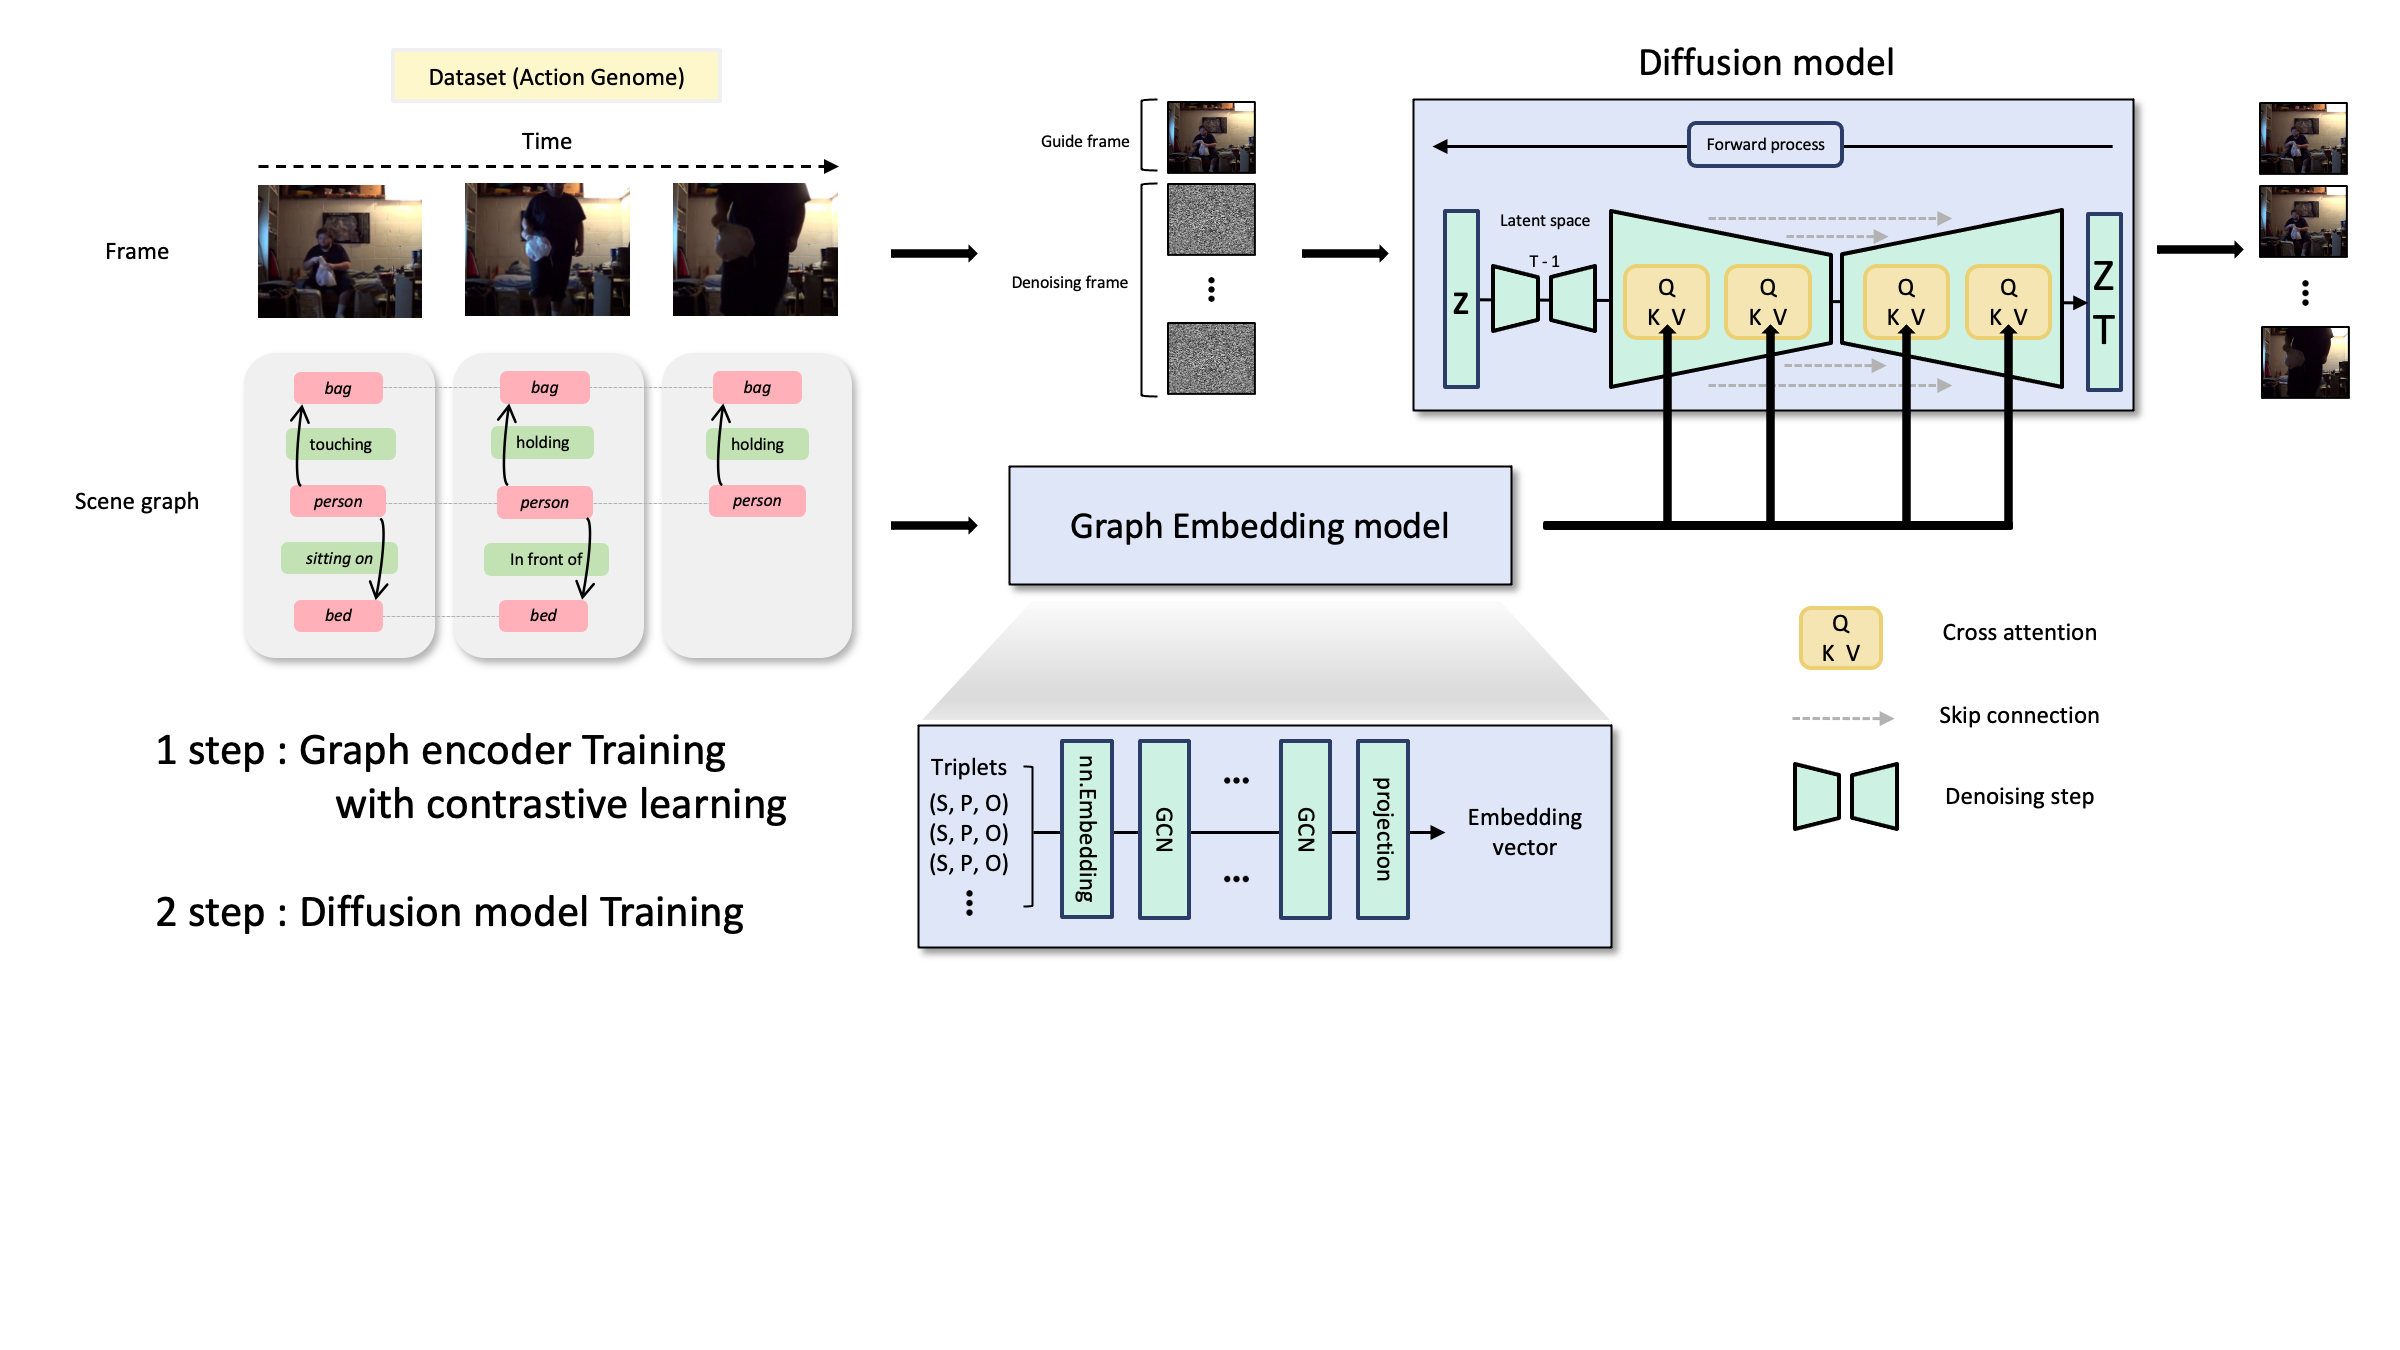

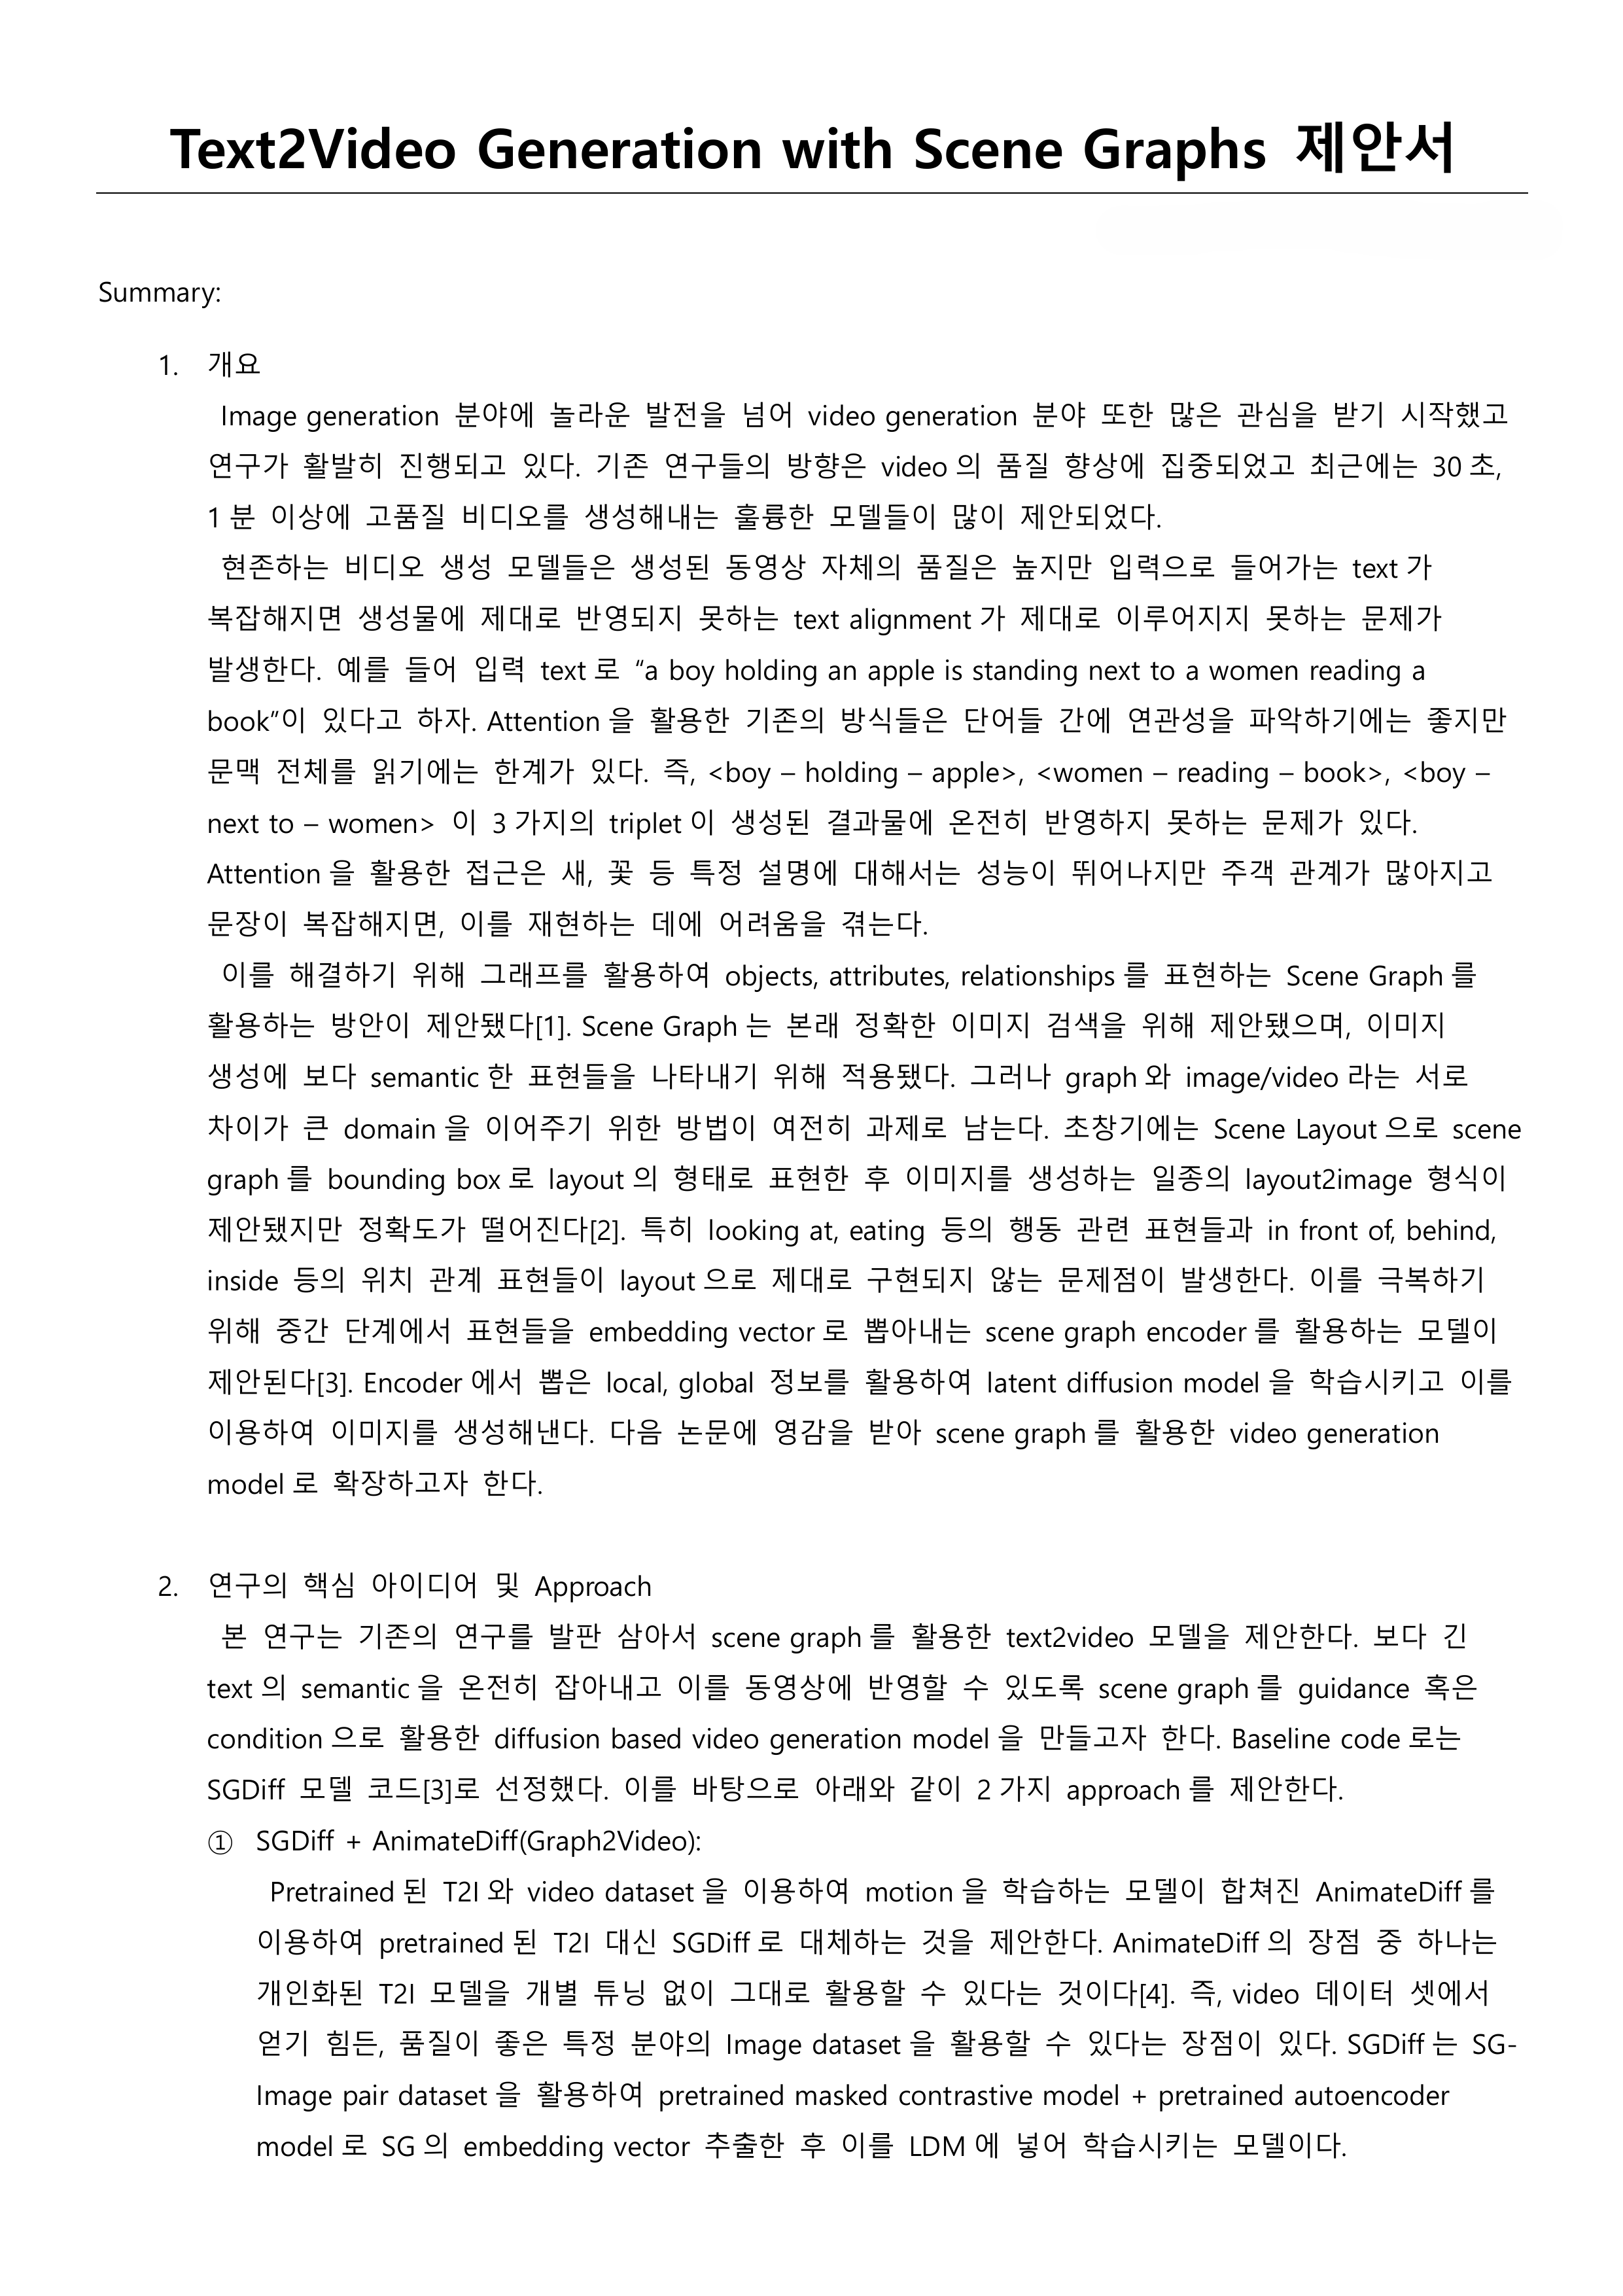
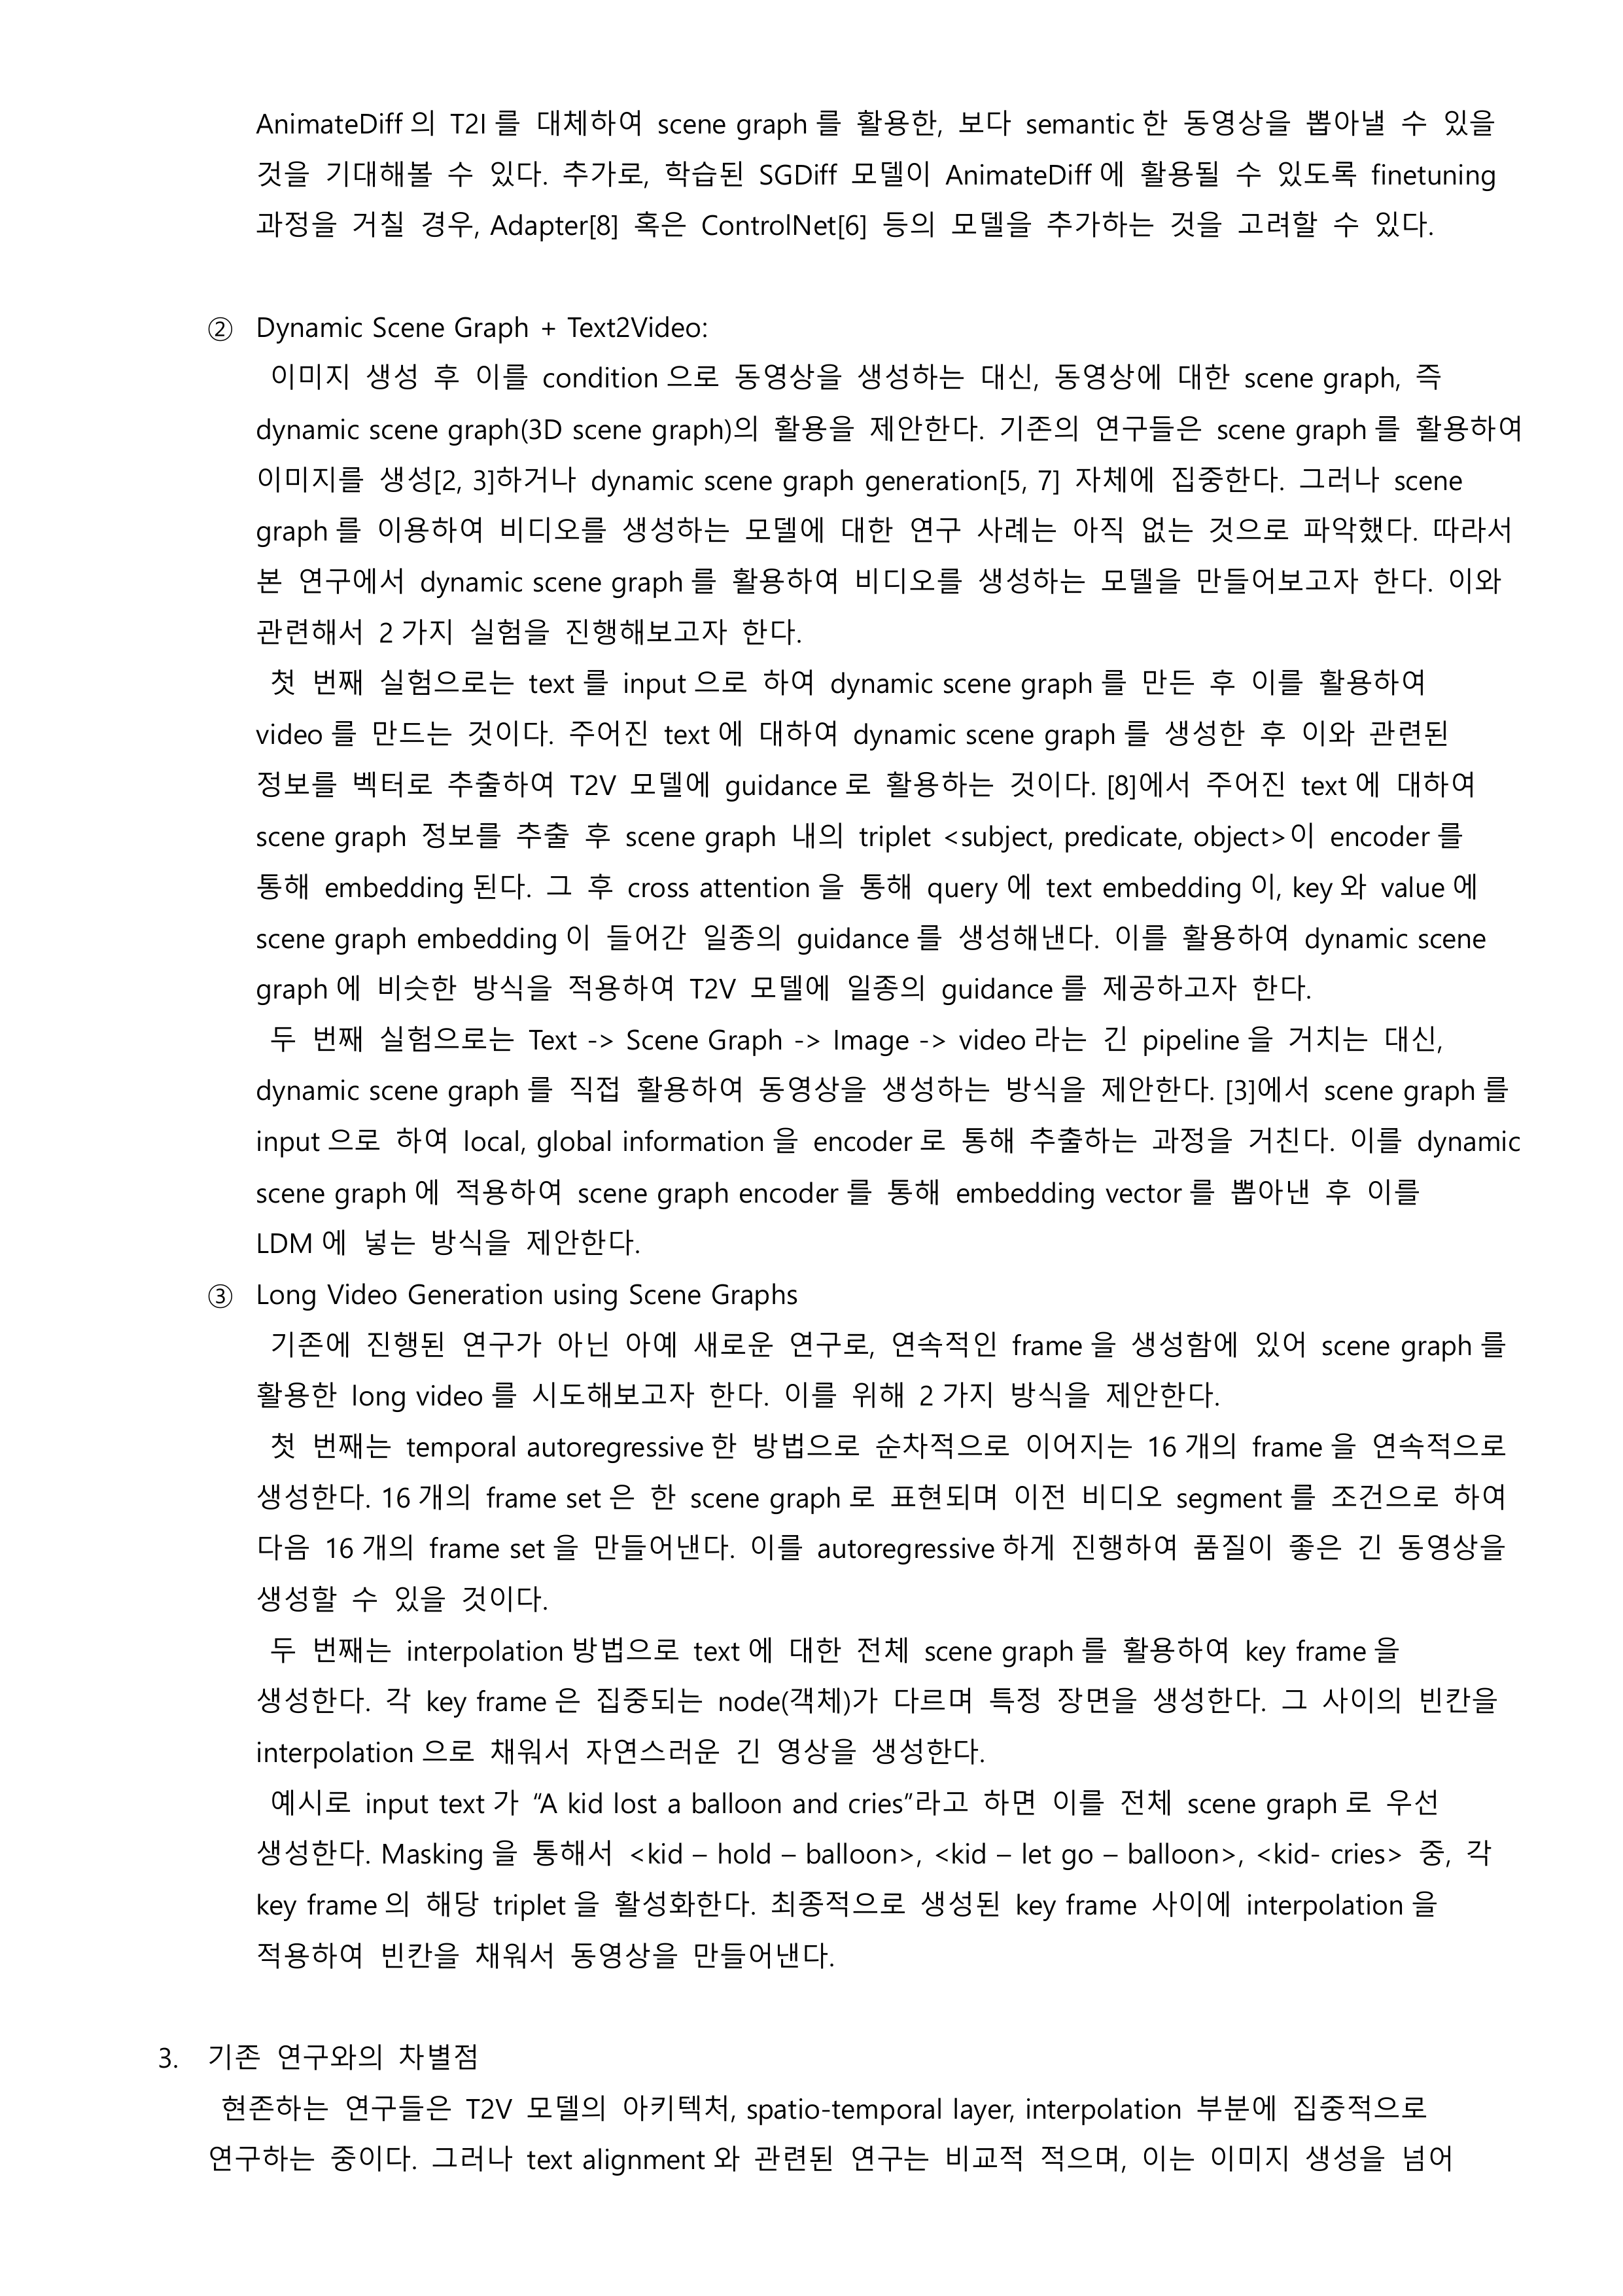
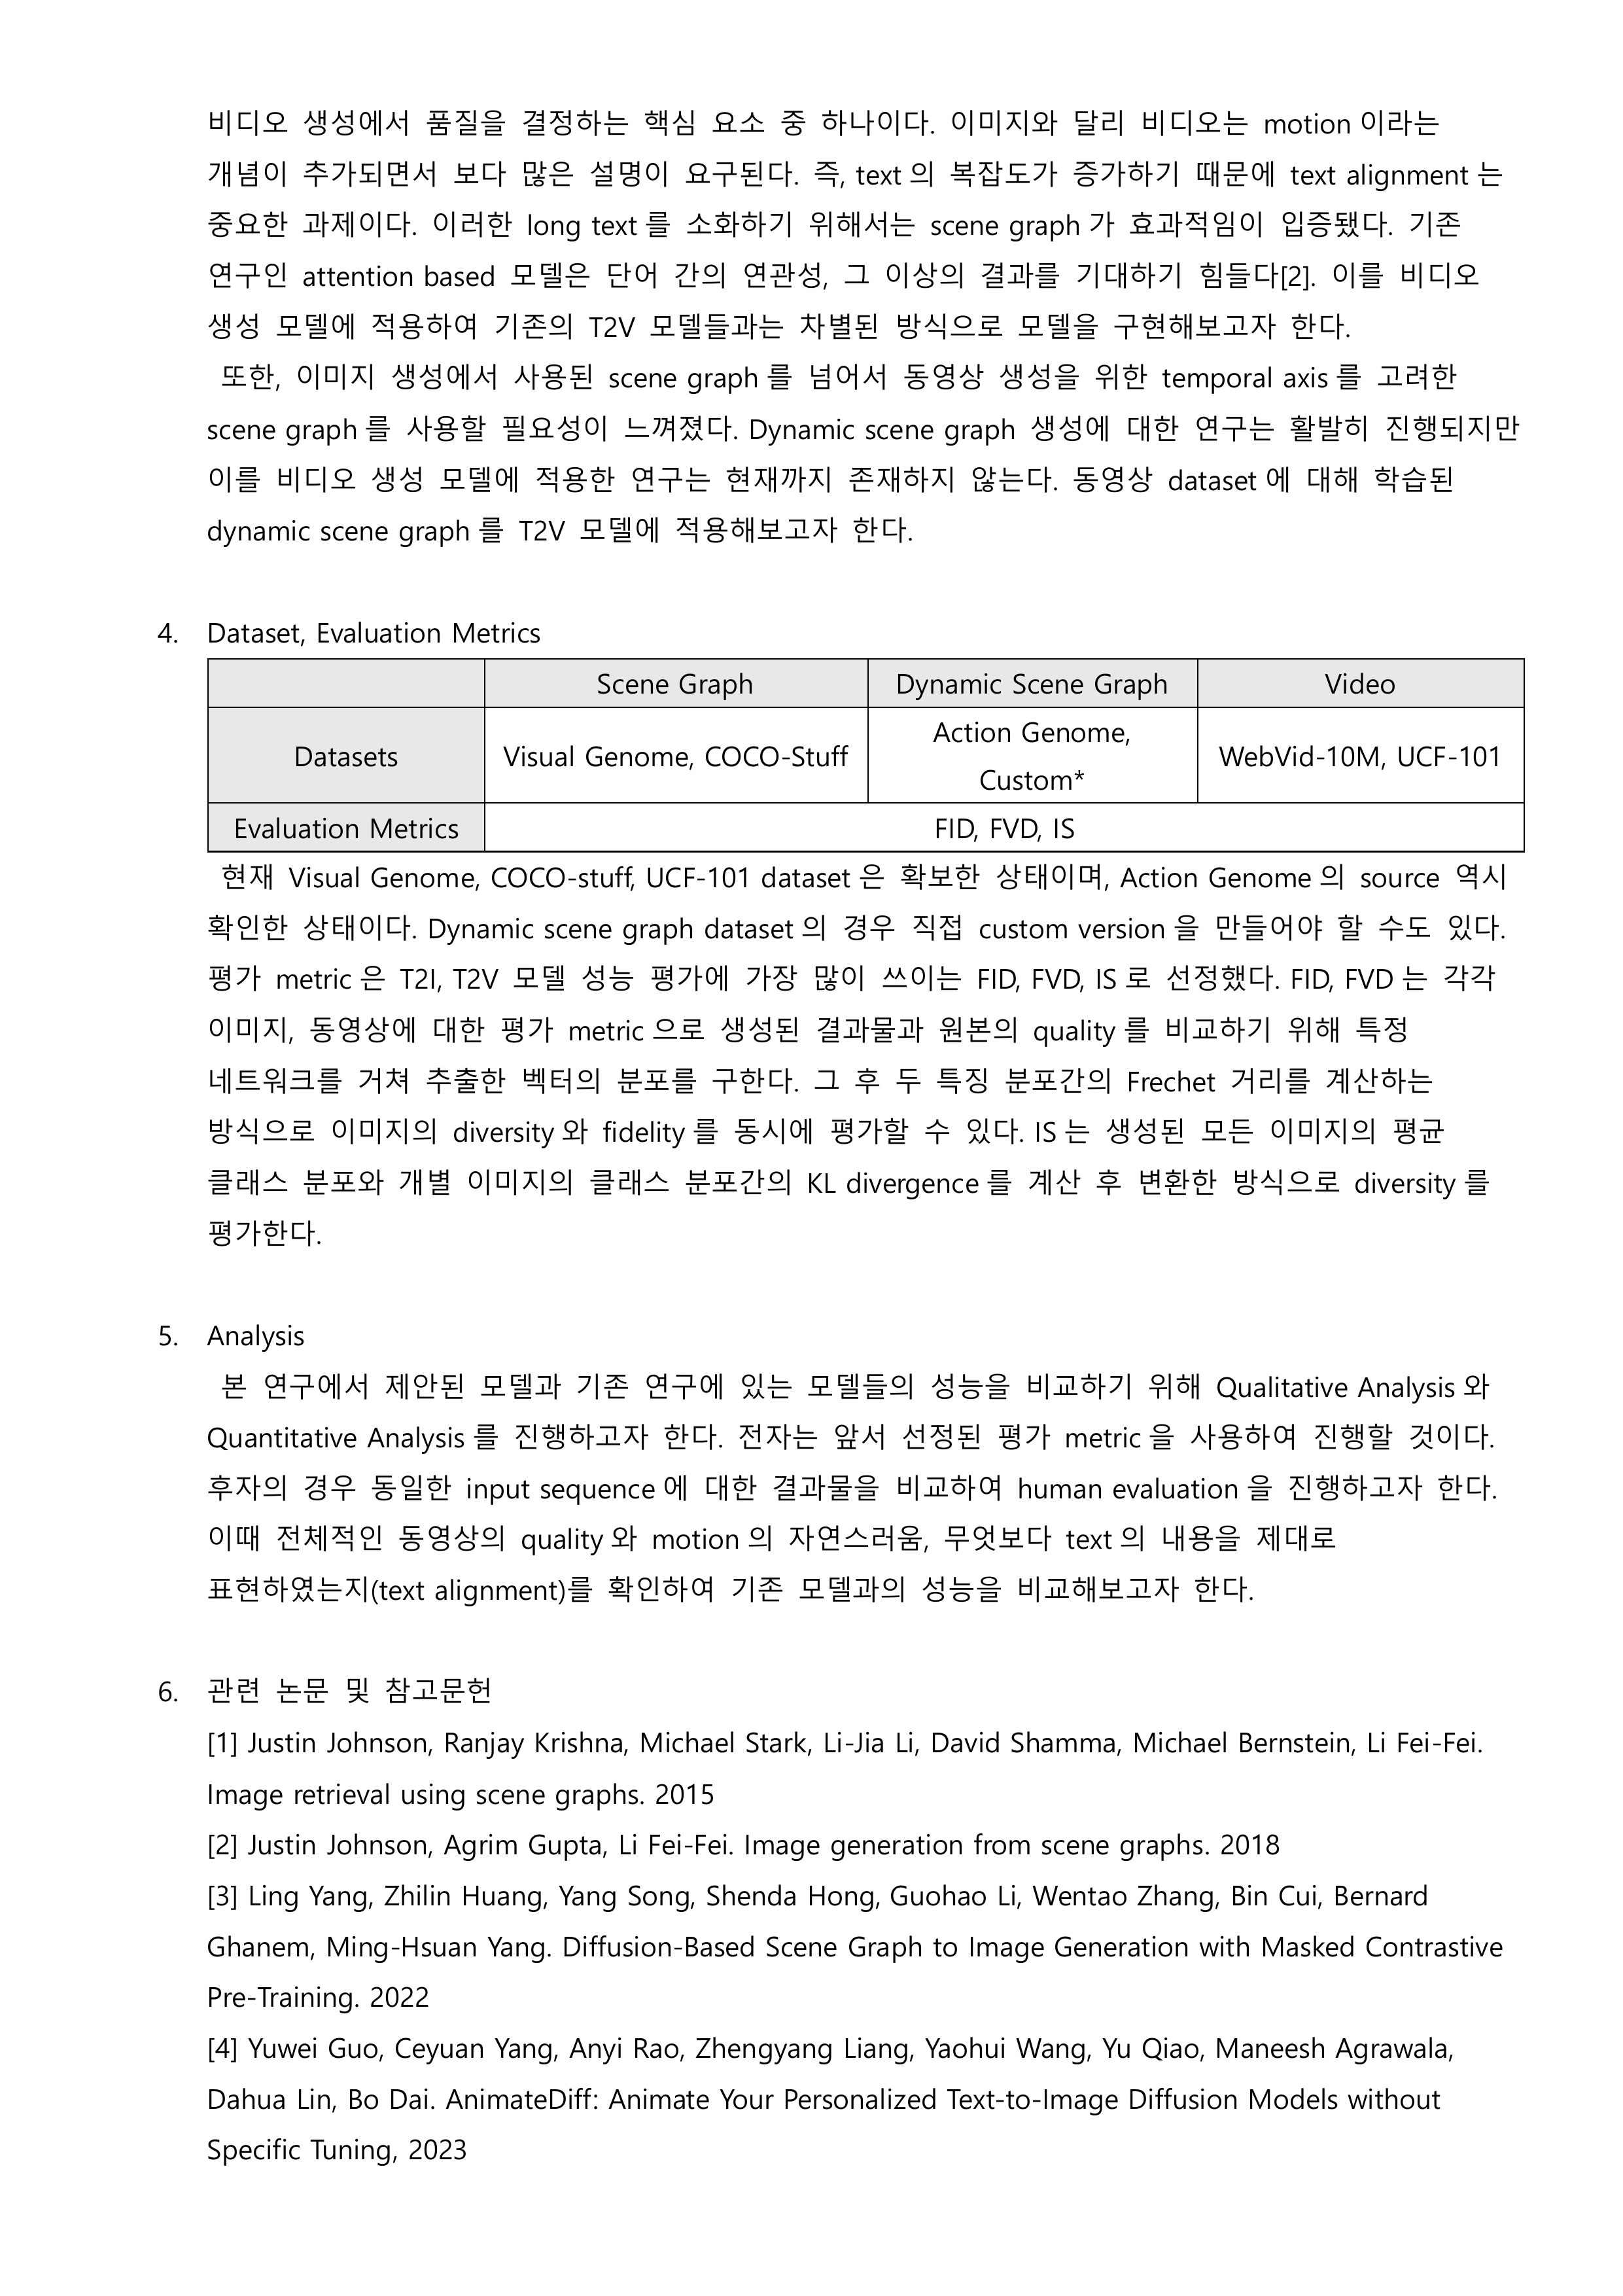
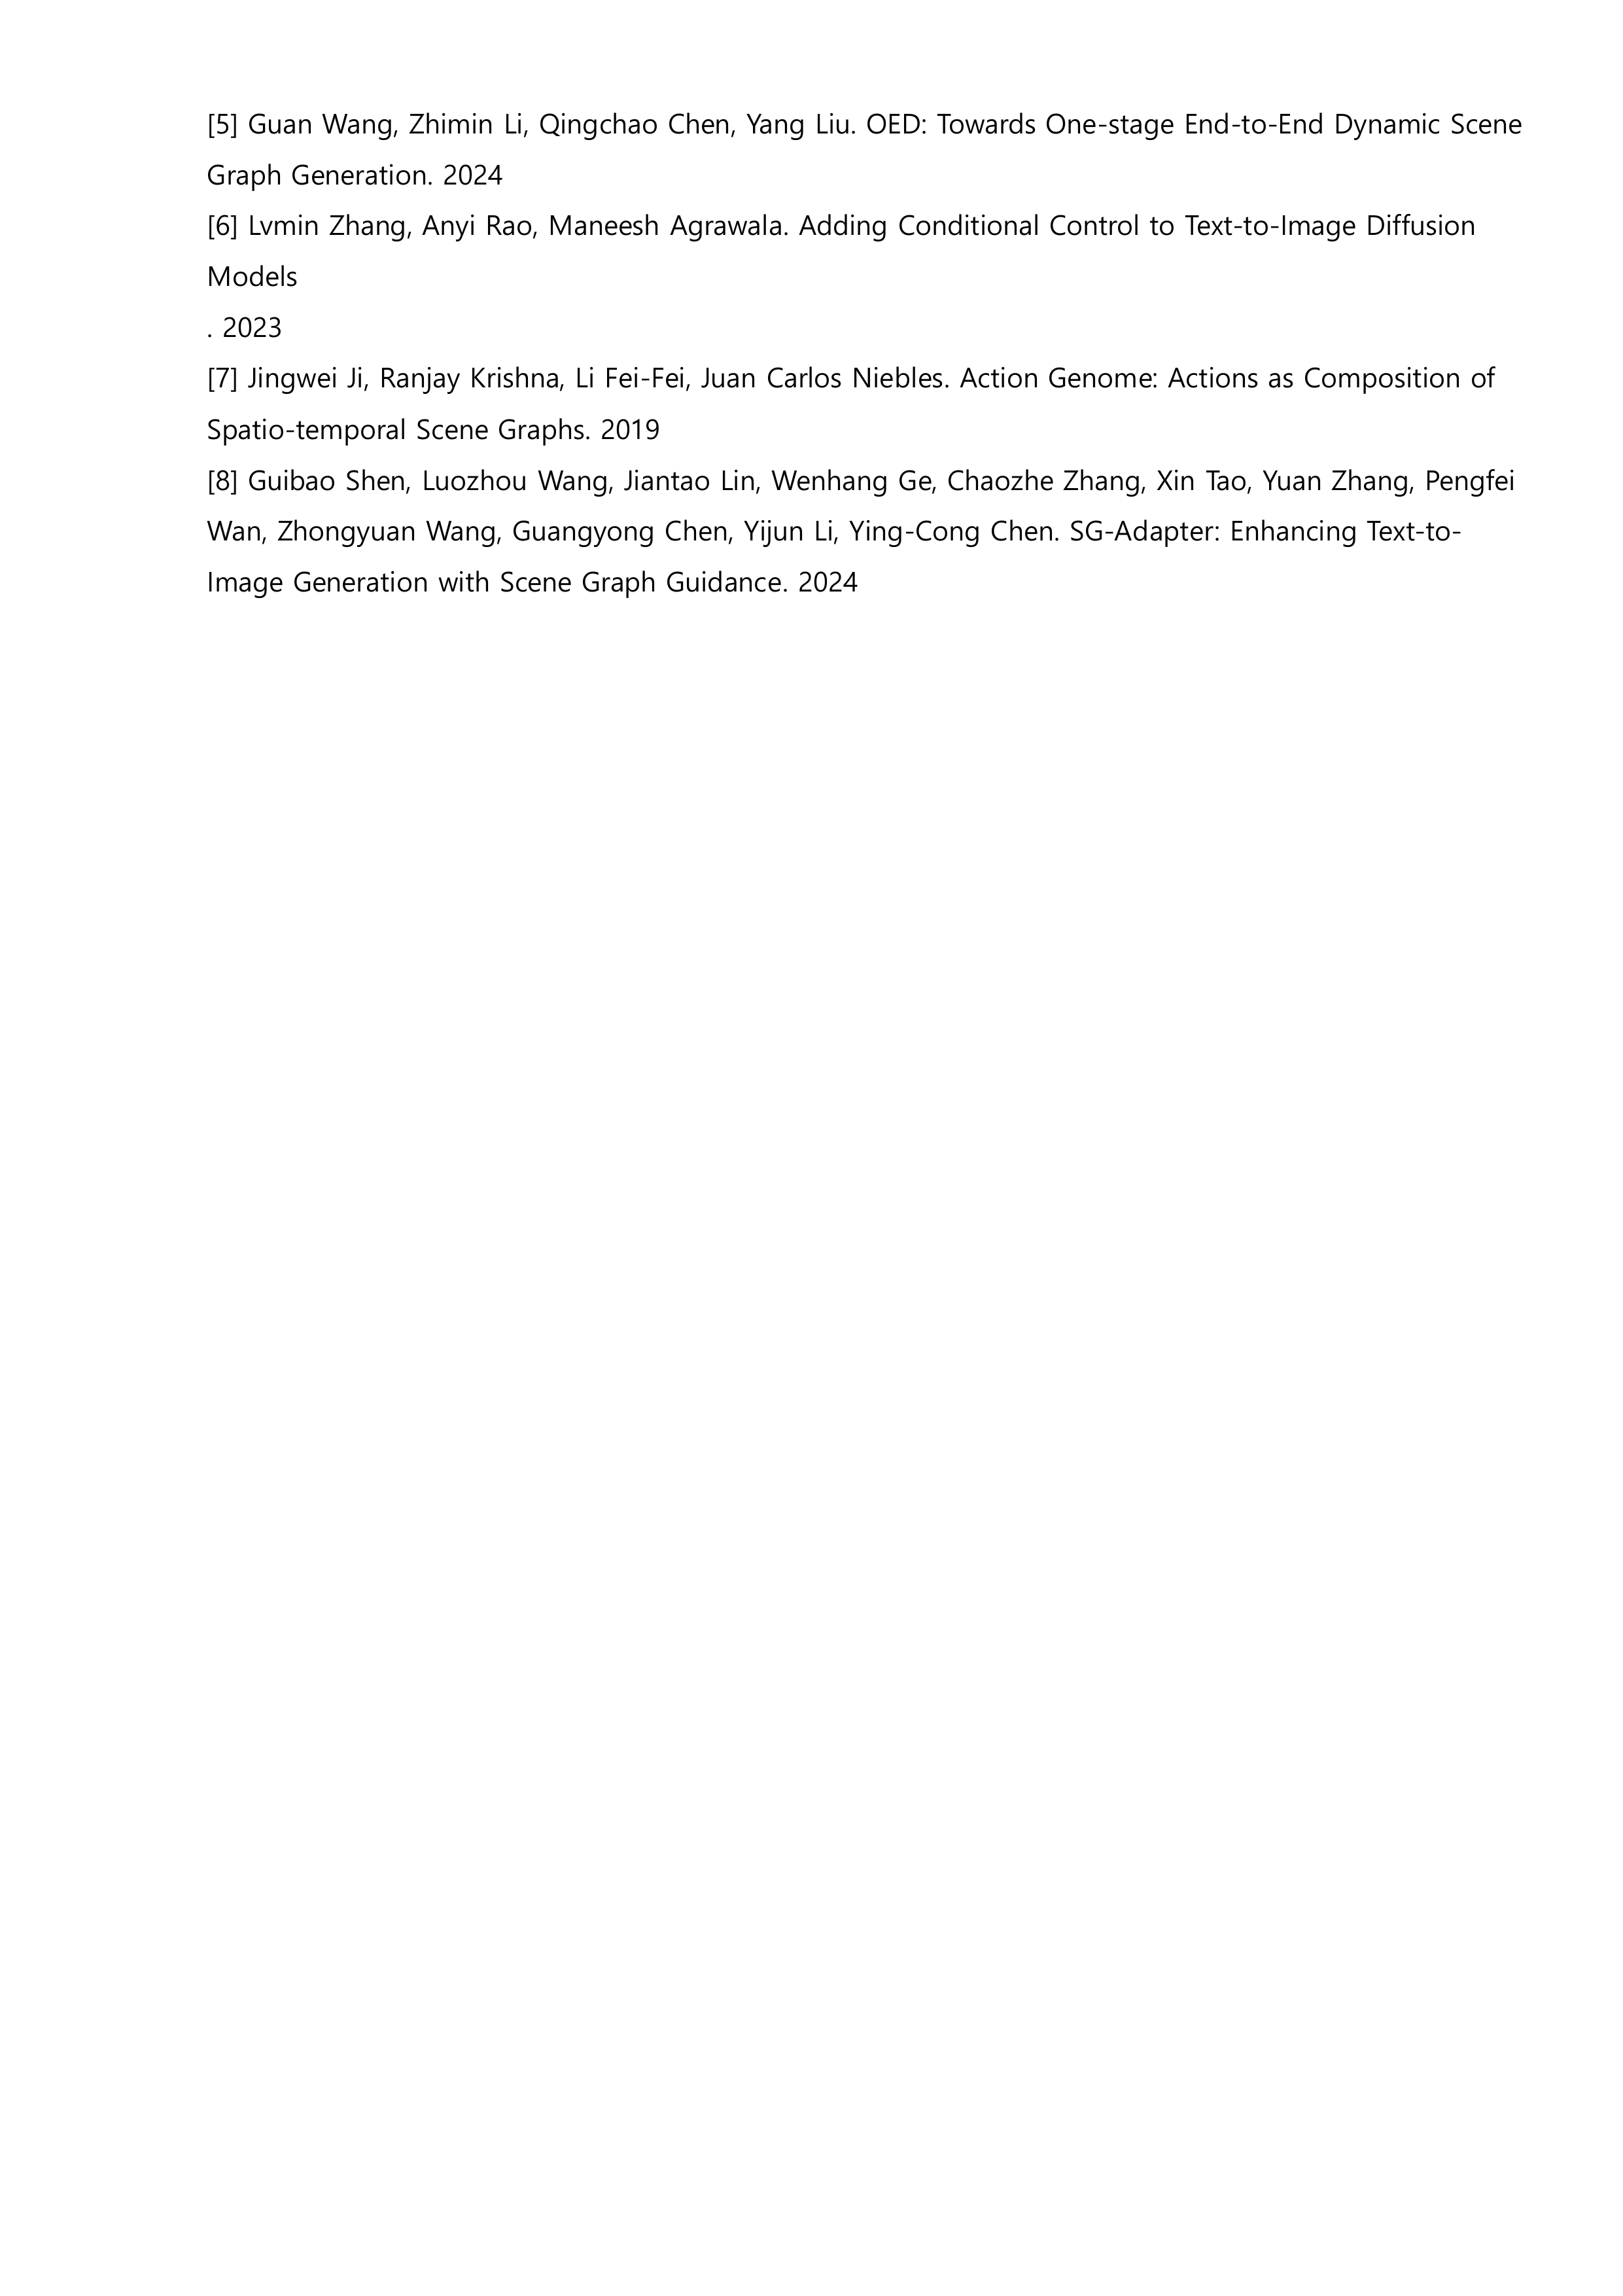
PDF Page 1

다음은 PDF 파일을 PNG로 변환하여 업로드 됩니다.

PDF Page 1 PDF Page 2 PDF Page 3 PDF Page 4

Categories: Project

Updated: November 1, 2024

Share on

Twitter Facebook LinkedIn
Previous Next

You may also enjoy

[논문분석] E2E Segmenter: Joint Segmenting and Decoding for Long-Form ASR

July 23, 2025

VAD(Voice Activity Detector)와 Streaming End-to-end (E2E) models for ASR을 통합해 성능 향상

[논문분석] Efficient Streaming LLM for Speech Recognition

July 22, 2025

ASR에 Decoder를 LLM으로 사용, LoRA finetuning

[논문분석] Real Time Speech Enhancement in the Waveform Domain

July 20, 2025

CPU에서도 실시간으로 동작하는 Sound Enhancement model

[논문분석] Fast Context-Biasing for CTC and Transducer ASR models with CTC-based Word Spotter

July 14, 2025

neural contextual adapter를 활용한 context-biasing

© 2026 Jongha Kim · Seoul, Republic of Korea

Email GitHub LinkedIn RSS